
AdaBoost, short for Adaptive Boosting, builds a strong classifier out of many weak ones. Each new weak model concentrates on the examples the previous ones got wrong, and the final prediction is a weighted vote. It was introduced by Yoav Freund and Robert Schapire in the mid-1990s and was the first boosting algorithm to work well in practice.
This guide explains the algorithm, works through it by hand on ten data points, then uses it in Python with scikit-learn. Every output shown is what the code printed when we ran it.
How AdaBoost works
AdaBoost usually uses decision stumps as its weak learners: trees with a single split, such as “if x < 3.5 predict +1, otherwise −1”. A stump on its own is barely better than guessing. AdaBoost repeats four steps:
- Give every training example the same weight.
- Fit a stump that minimizes the weighted error.
- Give that stump a say in the final vote, called alpha, based on how accurate it was.
- Increase the weights of the examples it got wrong and decrease the rest, so the next stump focuses on the hard cases. Repeat.
The formulas
For a stump with weighted error ε (epsilon), its vote weight is:
alpha = 0.5 * ln((1 - ε) / ε)A stump with 30% error gets alpha = 0.42; one with 10% error gets alpha = 1.10. A stump no better than chance (50% error) gets alpha = 0 and has no say.
Each example’s weight is then updated, where y is the true label (+1 or −1) and h(x) is the stump’s prediction:
w_new = w * exp(-alpha * y * h(x)) then divide all weights by their sumWhen the stump is right, y · h(x) = +1 and the weight shrinks. When it’s wrong, y · h(x) = −1 and the weight grows. The final prediction is the sign of the weighted vote:
F(x) = sign(alpha_1 * h_1(x) + alpha_2 * h_2(x) + ... + alpha_T * h_T(x))A numerical example, step by step
Take ten points on a line, x = 1 to 10, with these labels:
| x | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 |
|---|---|---|---|---|---|---|---|---|---|---|
| y | +1 | +1 | +1 | −1 | −1 | −1 | +1 | +1 | +1 | −1 |
No single threshold can separate these, because the labels switch three times. Here’s AdaBoost from scratch in NumPy, run for three rounds:
import numpy as np

x = np.arange(1, 11)
y = np.array([1, 1, 1, -1, -1, -1, 1, 1, 1, -1])

def best_stump(x, y, w):
    # Try every threshold and direction; keep the one with the lowest weighted error
    best = None
    for t in np.arange(0.5, 11, 1.0):
        for sign in (1, -1):
            pred = np.where(x < t, sign, -sign)
            err = w[pred != y].sum()
            if best is None or err < best[0]:
                best = (err, t, sign, pred)
    return best

w = np.full(10, 0.1)          # start with equal weights
F = np.zeros(10)              # running weighted vote
for round_ in range(1, 4):
    err, t, sign, pred = best_stump(x, y, w)
    alpha = 0.5 * np.log((1 - err) / err)
    F += alpha * pred
    rule = f"x < {t}: {sign:+d} else {-sign:+d}"
    print(f"round {round_}: {rule}, error {err:.3f}, alpha {alpha:.3f}")
    w = w * np.exp(-alpha * y * pred)
    w = w / w.sum()
    print("  new weights:", w.round(3))
    print("  ensemble accuracy:", (np.sign(F) == y).mean())
Output:
round 1: x < 3.5: +1 else -1, error 0.300, alpha 0.424
  new weights: [0.071 0.071 0.071 0.071 0.071 0.071 0.167 0.167 0.167 0.071]
  ensemble accuracy: 0.7
round 2: x < 9.5: +1 else -1, error 0.214, alpha 0.650
  new weights: [0.045 0.045 0.045 0.167 0.167 0.167 0.106 0.106 0.106 0.045]
  ensemble accuracy: 0.7
round 3: x < 6.5: -1 else +1, error 0.182, alpha 0.752
  new weights: [0.125 0.125 0.125 0.102 0.102 0.102 0.065 0.065 0.065 0.125]
  ensemble accuracy: 1.0
What happened in each round
- Round 1. The best stump predicts +1 for x < 3.5. It misclassifies x = 7, 8 and 9, so ε = 3 × 0.1 = 0.30 and alpha = 0.5 × ln(0.7 / 0.3) = 0.424. Those three points’ weights rise from 0.1 to 0.167, and the other seven fall to 0.071.
- Round 2. Because 7, 8 and 9 now weigh more, the best stump changes to x < 9.5. It misses x = 4, 5 and 6, which each weigh 0.071, so ε = 0.214 and alpha = 0.650.
- Round 3. Now 4, 5 and 6 are heavy, and the best stump is x < 6.5 predicts −1. It misses x = 1, 2, 3 and 10 (weighted error 0.182), and gets alpha = 0.752.
After three rounds the weighted vote classifies all ten points correctly, though no single stump got more than 70% right on its own. That’s boosting in a nutshell.
One detail if you compare with scikit-learn’s code: it uses alpha = ln((1 - ε) / ε), without the 0.5, and only increases the weights of misclassified points. After normalizing, the weights and the final predictions come out the same.
AdaBoost in Python with scikit-learn
pip install scikit-learn numpy matplotlibWe’ll use the breast cancer dataset that ships with scikit-learn: 569 tumors described by 30 measurements and labelled malignant (0) or benign (1).
from sklearn.datasets import load_breast_cancer
from sklearn.model_selection import train_test_split

X, y = load_breast_cancer(return_X_y=True)
print(X.shape, np.bincount(y))

X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.25, random_state=0, stratify=y
)
Output:
(569, 30) [212 357]Train the model
from sklearn.ensemble import AdaBoostClassifier
from sklearn.tree import DecisionTreeClassifier

stump = DecisionTreeClassifier(max_depth=1)
ada = AdaBoostClassifier(estimator=stump, n_estimators=200, learning_rate=0.5, random_state=0)
ada.fit(X_train, y_train)

print("one stump:", round(stump.fit(X_train, y_train).score(X_test, y_test), 3))
print("AdaBoost:", round(ada.score(X_test, y_test), 3))
Output:
one stump: 0.888
AdaBoost: 0.951
One stump gets 88.8% of the test set right. Two hundred stumps combined by AdaBoost get 95.1%.
Watch accuracy grow, stump by stump
staged_score returns the test accuracy after each added stump, which shows how the ensemble improves as it grows:
test_scores = list(ada.staged_score(X_test, y_test))
for n in [1, 5, 10, 25, 50, 100, 200]:
    print(n, round(test_scores[n - 1], 3))
Output:
1 0.888
5 0.944
10 0.951
25 0.944
50 0.937
100 0.937
200 0.951
import matplotlib.pyplot as plt
fig, ax = plt.subplots(figsize=(7, 4))
ax.plot(range(1, len(test_scores) + 1), test_scores)
ax.set_xlabel("Number of stumps")
ax.set_ylabel("Test accuracy")
plt.show()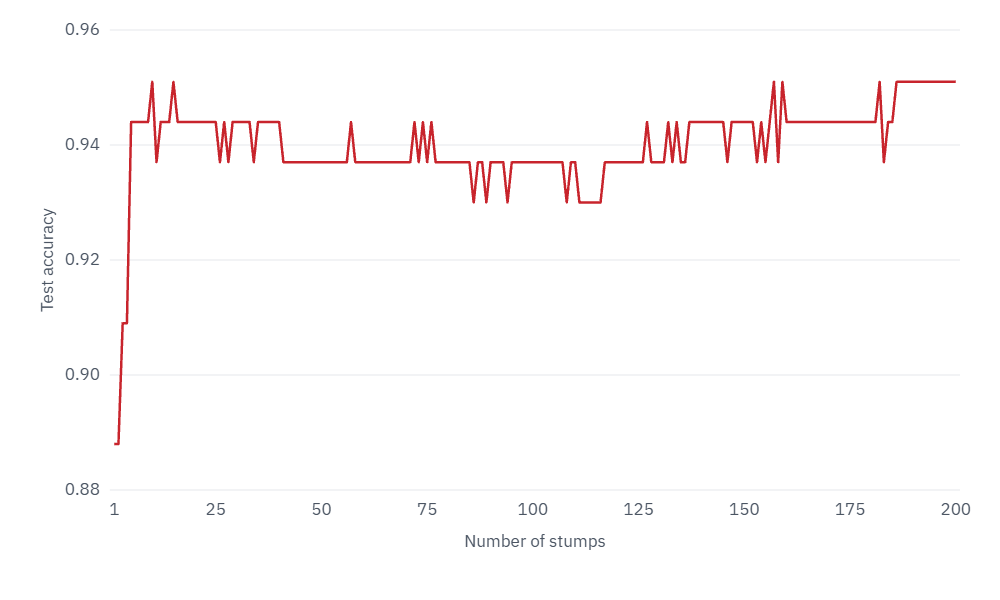
Most of the improvement comes from the first ten stumps. After that the test score moves up and down by one or two test cases. With 143 test rows, each one is worth 0.7 percentage points, so don’t read much into the small wiggles.
Tune n_estimators and learning_rate
The two settings that matter most are n_estimators, the number of stumps, and learning_rate, which shrinks each stump’s alpha. A smaller learning rate needs more stumps but is often more stable. Use cross-validation rather than a single split to compare them:
from sklearn.model_selection import cross_val_score

for lr in [0.1, 0.5, 1.0]:
    for n in [50, 200]:
        model = AdaBoostClassifier(estimator=DecisionTreeClassifier(max_depth=1),
                                   n_estimators=n, learning_rate=lr, random_state=0)
        print(lr, n, cross_val_score(model, X, y, cv=5).mean().round(3))
Output:
0.1 50 0.947
0.1 200 0.96
0.5 50 0.963
0.5 200 0.975
1.0 50 0.967
1.0 200 0.977| learning_rate | 50 stumps | 200 stumps |
|---|---|---|
| 0.1 | 94.7% | 96.0% |
| 0.5 | 96.3% | 97.5% |
| 1.0 | 96.7% | 97.7% |
More stumps helped at every learning rate. A learning rate of 0.1 with 50 stumps underfits: it simply hasn’t taken enough steps. On a new problem, start with 0.5 and 200, then adjust.
How AdaBoost compares
from sklearn.ensemble import RandomForestClassifier, GradientBoostingClassifier
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

models = {
    "Decision stump": DecisionTreeClassifier(max_depth=1),
    "Decision tree": DecisionTreeClassifier(random_state=0),
    "AdaBoost": AdaBoostClassifier(estimator=DecisionTreeClassifier(max_depth=1),
                                   n_estimators=200, learning_rate=0.5, random_state=0),
    "Random forest": RandomForestClassifier(n_estimators=300, random_state=0),
    "Gradient boosting": GradientBoostingClassifier(random_state=0),
    "Logistic regression": make_pipeline(StandardScaler(), LogisticRegression(max_iter=1000)),
}
for name, model in models.items():
    print(f"{name:20} {cross_val_score(model, X, y, cv=5).mean():.3f}")
Output:
Decision stump       0.903
Decision tree        0.917
AdaBoost             0.975
Random forest        0.963
Gradient boosting    0.963
Logistic regression  0.981
AdaBoost lifts a 90% stump to 97.5%, slightly ahead of random forest and gradient boosting with default settings. But plain logistic regression on scaled features does best of all at 98.1%. This dataset is close to linearly separable, so a simple linear model is hard to beat. Always try a simple baseline before reaching for an ensemble.
Which features matter
names = load_breast_cancer().feature_names
top = np.argsort(ada.feature_importances_)[::-1][:5]
for i in top:
    print(f"{names[i]:25} {ada.feature_importances_[i]:.3f}")
Output:
worst texture             0.150
radius error              0.107
worst concave points      0.090
worst area                0.085
mean concave points       0.080
The importance of a feature is the share of the total vote carried by the stumps that split on it. The features describe the texture, size and shape of cell nuclei in digitized images of the tumor samples. The worst features, the largest value found in each sample, carry the most weight.
The main weakness: noisy labels
Because AdaBoost keeps increasing the weight of misclassified examples, a mislabelled example can end up dominating later rounds. To test this, mislabel 15% of the training rows and retrain:
rng = np.random.default_rng(0)
y_noisy = y_train.copy()
flip = rng.choice(len(y_noisy), size=int(0.15 * len(y_noisy)), replace=False)
y_noisy[flip] = 1 - y_noisy[flip]          # mislabel 15% of the training rows

for name in ["AdaBoost", "Random forest"]:
    clean = models[name].fit(X_train, y_train).score(X_test, y_test)
    noisy = models[name].fit(X_train, y_noisy).score(X_test, y_test)
    print(f"{name:14} clean {clean:.3f}  noisy {noisy:.3f}")
Output:
AdaBoost       clean 0.951  noisy 0.916
Random forest  clean 0.944  noisy 0.944
AdaBoost loses 3.5 points of test accuracy; random forest loses nothing. If your labels are unreliable, as with crowd-sourced annotations or data entered by hand, prefer random forests or gradient boosting with subsampling.
When to use AdaBoost
| Use AdaBoost when | Choose something else when |
|---|---|
| The data is small or medium-sized and fairly clean | Labels are noisy or there are extreme outliers |
| You want a strong model with only two settings to tune | You need the best accuracy on large tabular data: try XGBoost, LightGBM or CatBoost |
| You want to learn how boosting works | A linear model already does as well, as it did here |
AdaBoost vs gradient boosting
Both build models in sequence, each correcting the last. AdaBoost does it by re-weighting the training examples. Gradient boosting fits each new tree to the remaining errors (the gradient of the loss) and can use any differentiable loss function. That flexibility is why gradient boosting and its fast descendants largely replaced AdaBoost for serious tabular work, while AdaBoost remains the clearest way to understand the idea of boosting.
Common mistakes
- Using deep trees as weak learners. AdaBoost works best with weak models. Deep trees overfit quickly and leave little for later rounds to correct.
- Judging by a single train/test split. The test curve above moves by a full point between neighboring sizes. Use cross-validation.
- Ignoring label quality. A few wrong labels can steer the whole ensemble, as the noise test showed.
- Skipping a simple baseline. Here, logistic regression beat every ensemble.
Keep learning
- Decision trees explained: the building block of AdaBoost
- Random forests: the bagging alternative to boosting
- Gradient boosting machines
- XGBoost vs LightGBM vs CatBoost: benchmark results
The scikit-learn user guide on AdaBoost documents the AdaBoostClassifier used in this tutorial.
FAQ
What is AdaBoost in simple terms?
A method that trains many very simple models one after another. Each new model pays more attention to the examples the earlier ones got wrong, and all of them vote on the final answer, with better models getting a bigger vote.
What is the alpha in AdaBoost?
Alpha is a weak learner’s weight in the final vote. It’s calculated as 0.5 × ln((1 − ε) / ε), where ε is the learner’s weighted error. More accurate learners get larger alphas.
What does the learning rate do in AdaBoost?
It multiplies each learner’s alpha, shrinking its contribution. Lower values need more learners but often generalize better. In our tests, 0.5 to 1.0 with 200 stumps worked best.
Why does AdaBoost use decision stumps?
Boosting needs learners that are only slightly better than chance, so each round has something left to correct. Stumps are fast to train and weak by design. You can use deeper trees, but they tend to overfit sooner.
Is AdaBoost still used?
Less than before. For most tabular problems, gradient boosting libraries such as XGBoost and LightGBM are more accurate and handle noisy data better. AdaBoost is still a solid choice on small, clean datasets and the best way to learn how boosting works.
