
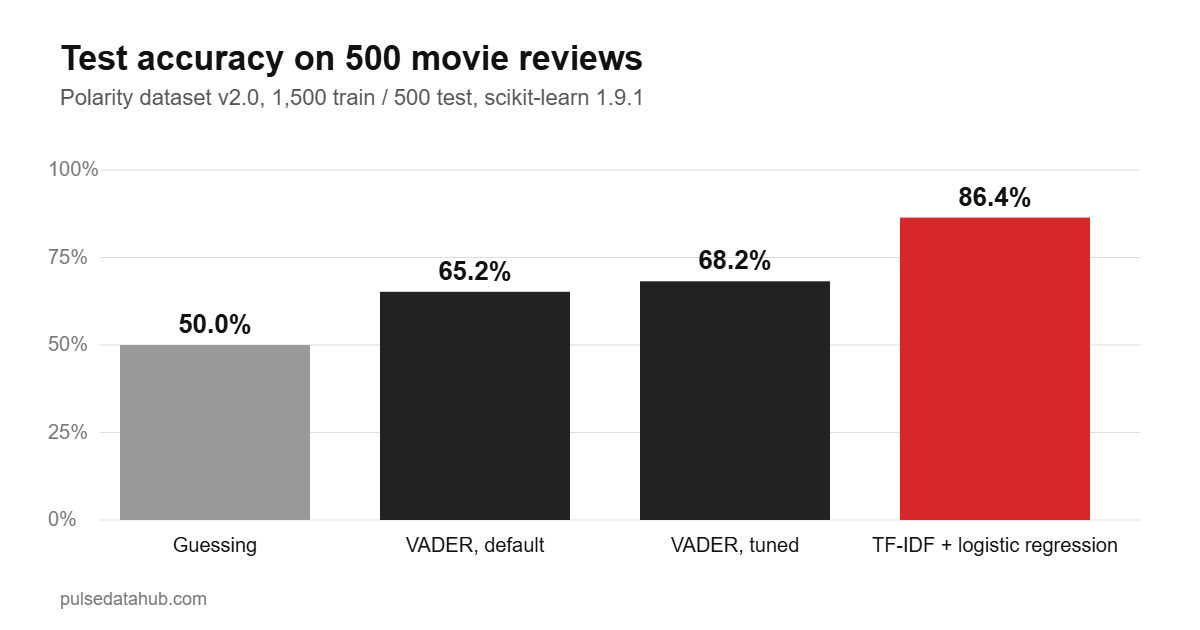
Sentiment analysis with Python can be done two ways: apply a ready-made rule-based scorer, or train a model on labelled text. This tutorial runs both on the same 2,000 real movie reviews and shows how they compare. The result is not what most tutorials suggest: the ready-made scorer is right only 65% of the time on this data, and a simple trained model reaches 86%.
The data is the Polarity Dataset v2.0 of Pang and Lee, 1,000 positive and 1,000 negative movie reviews (dataset page), also distributed in the NLTK data repository. Every number below was produced on 20 November 2026 with scikit-learn 1.9.1, pandas 3.0.5 and vaderSentiment 3.3.2.
1. Load the reviews
import pathlib
import pandas as pd

rows = []
for label in ["neg", "pos"]:
    for f in sorted(pathlib.Path("movie_reviews", label).glob("*.txt")):
        rows.append((f.read_text(errors="ignore"), label == "pos"))
df = pd.DataFrame(rows, columns=["text", "pos"])
print(df.shape, df.pos.mean())
print(df.text.str.split().str.len().describe().round(0)[["mean", "50%", "min", "max"]].to_dict())
(2000, 2) 0.5
{'mean': 746.0, '50%': 696.0, 'min': 17.0, 'max': 2678.0}2,000 reviews, exactly balanced, so guessing gets 50%. They are long: 746 words on average, from 17 to 2,678. That length will matter later.
2. Split before you do anything else
from sklearn.model_selection import train_test_split

train, test = train_test_split(df, test_size=0.25, stratify=df.pos, random_state=42)
print(len(train), len(test))
1500 5003. Approach one: a rule-based scorer (VADER)
VADER is a lexicon of words with sentiment scores plus rules for negation, capitals and punctuation. It needs no training. It returns a compound score from -1 to +1, and we call a review positive if the score is above 0.
from vaderSentiment.vaderSentiment import SentimentIntensityAnalyzer
from sklearn.metrics import accuracy_score, confusion_matrix

sia = SentimentIntensityAnalyzer()
test = test.copy()
test["vader"] = test.text.map(lambda t: sia.polarity_scores(t)["compound"])
pred = test.vader > 0
print(round(accuracy_score(test.pos, pred), 3))
print(confusion_matrix(test.pos, pred))
print(round(pred.mean(), 3))
0.652
[[118 132]
[ 42 208]]
0.68Accuracy is 65.2%, only 15 points above guessing. The confusion matrix shows why: of 250 negative reviews it labels 132 positive. It calls 68% of all reviews positive although exactly half are. A long review contains both praise and complaints, and summing word scores over 746 words pushes almost everything above zero.
Can tuning the threshold fix it? Choosing the best cut-off on the training data gives 0.99 (a review counts as positive only if its score exceeds 0.99), which lifts test accuracy to 68.2%. That is better but still far from good. VADER was built for short social-media text (project page), and long reviews are outside what it was designed for. A tool used outside its intended domain is the most common reason a sentiment project disappoints.
4. Approach two: learn from labelled reviews
Now turn the text into numbers with TF-IDF, which weights each word by how informative it is, and train logistic regression on it. Putting both steps in one pipeline keeps the vocabulary learned from training data only (the same discipline as in our scikit-learn tutorial).
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline

model = make_pipeline(
    TfidfVectorizer(min_df=2, ngram_range=(1, 2), sublinear_tf=True),
    LogisticRegression(max_iter=2000, C=10),
)
model.fit(train.text, train.pos)
pred = model.predict(test.text)
print(round(accuracy_score(test.pos, pred), 3))
print(confusion_matrix(test.pos, pred))
0.864
[[216 34]
[ 34 216]]Test accuracy is 86.4%, and errors are symmetric: 34 negatives called positive and 34 positives called negative. Five-fold cross-validation on the training set gives 87.6% on average (folds 0.870, 0.890, 0.870, 0.877, 0.873), consistent with the test result. Using single words only, with no word pairs, gives 86.2%, so the extra complexity of bigrams bought almost nothing.
5. What did the model learn?
A linear model lets you read its most influential words:
import numpy as np

vec, lr = model[0], model[1]
names = np.array(vec.get_feature_names_out())
order = np.argsort(lr.coef_[0])
print(len(names))
print("negative:", list(names[order[:8]]))
print("positive:", list(names[order[-8:]][::-1]))
110116
negative: ['bad', 'worst', 'boring', 'nothing', 'script', 'plot', 'should have', 'the worst']
positive: ['great', 'very', 'perfect', 'the best', 'excellent', 'well', 'he is', 'as the']The vocabulary has 110,116 terms. The strongest negative words (bad, worst, boring) and positive words (great, perfect, excellent) make sense. But “script” and “plot” count as negative and “he is” and “as the” as positive. Those are patterns of how reviewers write about films in this particular corpus, not sentiment. This is why a model trained on movie reviews should not be trusted on tweets or product reviews without testing it there.
6. The two approaches compared
On the 500 test reviews, 287 were classified correctly by both models and 39 only by VADER. The trained model’s advantage comes from learning this domain’s vocabulary, which VADER’s general lexicon cannot.
7. Where both fail: short and tricky sentences
for s in ["The movie was good.",
          "The movie was not good.",
          "The movie was not bad at all.",
          "I expected a masterpiece and got a disaster.",
          "Great, another sequel nobody asked for."]:
    print(s, round(sia.polarity_scores(s)["compound"], 3),
          model.predict_proba([s])[0, 1].round(2))
The movie was good. 0.44 0.32
The movie was not good. -0.341 0.35
The movie was not bad at all. 0.431 0.19
I expected a masterpiece and got a disaster. 0.0 0.5
Great, another sequel nobody asked for. 0.625 0.47The first number is VADER’s score (above 0 is positive); the second is the trained model’s probability that the text is positive (above 0.5 is positive). The results are mixed. VADER handles “not good” and “not bad at all” correctly through its negation rule, but misses the contrast in the masterpiece and disaster sentence (0.0, neutral) and reads the sarcastic “Great, another sequel” as positive (0.625). The trained model, which learned from 700-word reviews, calls “The movie was good.” negative (0.32) and “not bad at all” negative (0.19). Short text is out of distribution for it, and no model here understands sarcasm.
8. Look at the mistakes
Accuracy hides what is going on. The most confident mistake of the trained model was a negative review of The Man Who Cried that it scored 0.79 positive; its opening lines are about Christina Ricci and the director’s earlier film, not a verdict. The most confident miss in the other direction was a positive review scored 0.25, which opens by recounting the box-office success of an earlier film. Read at least 20 wrong predictions in your own project. You will usually find labels that are debatable, reviews that discuss other films, and text the model was never meant to handle.
A practical checklist
- Start with a baseline (50% here) and a rule-based scorer, but test it on your own text, not on the examples in its README.
- Match the tool to the text: VADER for short social posts, a trained model for long, domain-specific text.
- Split before fitting, and keep vectorising inside a pipeline.
- Read the confusion matrix. VADER’s 132 false positives were invisible in the accuracy figure.
- Inspect top words for artefacts such as “script” or “he is”.
- Test on the kind of text you will really score, including short and sarcastic examples.
To build the text-processing skills this relies on, see natural language processing with Python. You can check any confusion matrix with our confusion matrix calculator.
Frequently asked questions
What is the best Python library for sentiment analysis?
There is no single best one. VADER is quick and needs no training but is built for short social text. scikit-learn with TF-IDF is a strong, simple baseline when you have labelled data. Large pretrained language models are another option; on this data we did not test them.
How accurate is sentiment analysis?
It depends heavily on the text. On these 500 movie reviews, VADER scored 65.2% and TF-IDF with logistic regression 86.4%. Sarcasm, mixed opinions and domain-specific wording lower accuracy for any method.
Do I need labelled data?
For a trained model, yes: here 1,500 labelled reviews. A rule-based scorer needs none, but you still need some labelled examples to check whether it works on your text.
